TL;DR
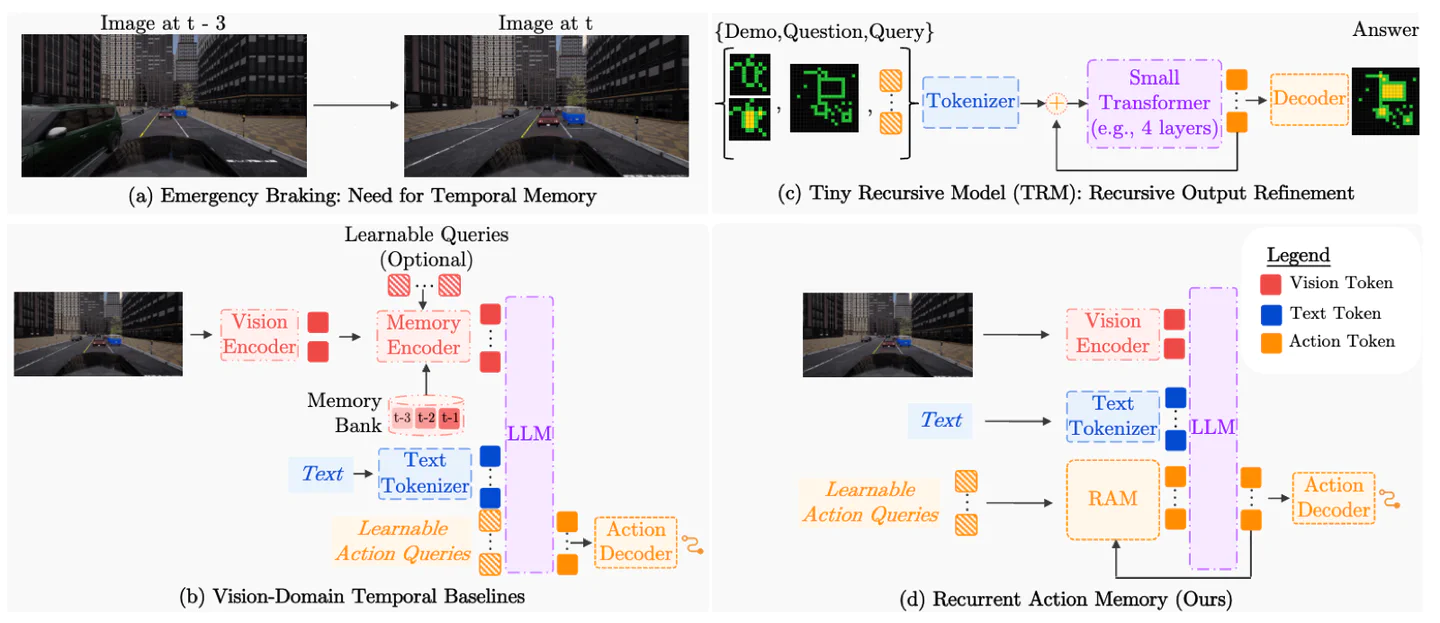
FIVE-VLA is a 641M-parameter vision-language-action model for driving that pairs an efficient high-resolution vision encoder with Recurrent Action Memory, a lightweight module conditioning action prediction on previous action tokens. It completes ~10% more routes without infractions on Bench2Drive than the previous state-of-the-art VLA while running 8-30x faster.
Type
Publication
Conference on Neural Information Processing Systems